
If you are a Gemini Advanced subscriber, you might have noticed a subtle new option lurking in your settings menu. Google has officially rolled out Smart Model Selection, a feature tucked away under the Advanced Settings tab designed to intelligently route your prompts behind the scenes.
While the primary goal is to help users squeeze more life out of their hourly usage caps, the move has ignited plenty of conversation across the AI community—especially among power users still eagerly tracking rumors around Google’s Gemini 3.5 Pro delays and upcoming model launches.
What Is Smart Model Selection?
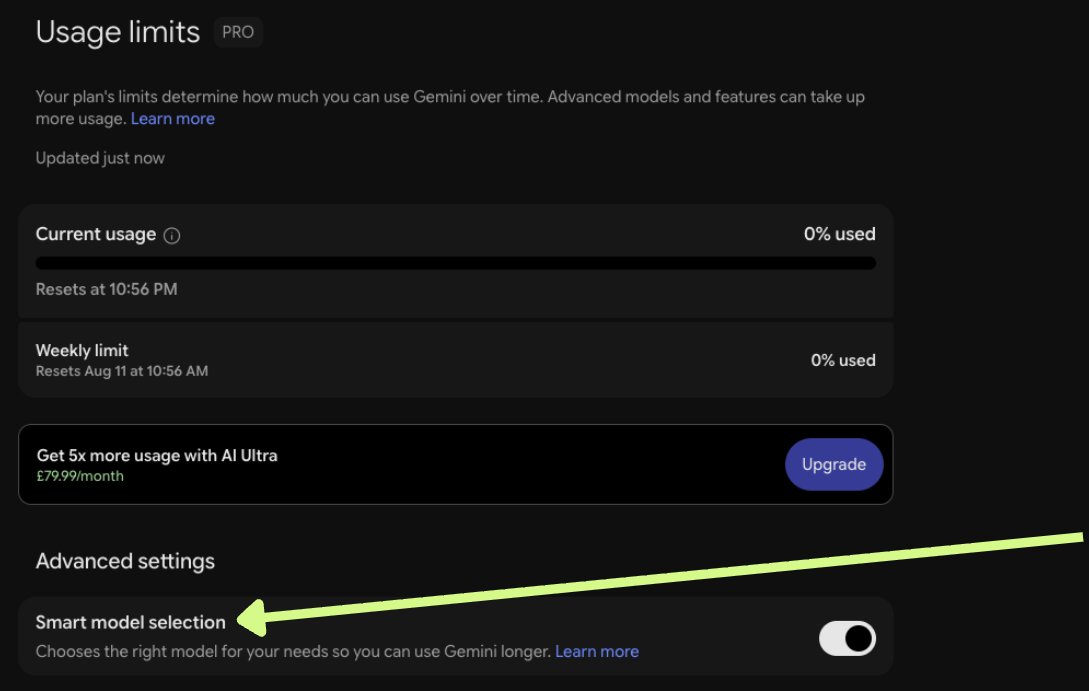
Instead of locking your entire session into a heavy reasoning engine or manually toggling down to a lighter option, the new Smart model selection toggle acts as an automated traffic controller for your queries.
When you submit a prompt, Google’s system quickly evaluates the underlying request. Simple tasks (like basic text edits, formatting, or straightforward Q&A) get offloaded to lighter, faster models like Flash. Meanwhile, complex tasks (like multi-step coding routines, mathematical proofs, or deep analytical research) get directed straight to the full Pro model.
                 ┌──────────────────────────┐
                 │    User Submits Query    │
                 └────────────┬─────────────┘
                              │
               ┌──────────────▼──────────────┐
               │    Smart Router Evaluates   │
               │   Complexity & Scope        │
               └──────────────┬─────────────┘
                              │
        ┌─────────────────────┴─────────────────────┐
        ▼                                           ▼
┌───────────────┐                           ┌───────────────┐
│ Simple Tasks  │                           │ Complex Tasks │
│ (Flash / Lite)│                           │  (Pro Engine) │
└───────────────┘                           └───────────────┘
Key Details at a Glance:
Dynamic Prompt Routing: Chooses the right model tailored specifically to each individual message rather than forcing a single model across the whole chat session.
Extended Usage Limits: Offloading everyday conversational tasks saves your high-tier tokens, giving you a significantly longer runway before hitting rate limits.
Off by Default: Google isn’t forcing this on anyone just yet. The toggle arrives turned OFF, so you have to manually opt-in if you want to try it out.
Smart Routing vs. Manual Model Selection
How does this new setup stack up against keeping things in manual mode? Here is a quick breakdown:
| Feature | Manual Model Selection | Smart Model Selection (Auto) |
| Model Control | Explicitly set by you for the entire chat | Dynamically chosen per prompt based on query intent |
| Response Speed | Subject to the default model speed (Pro is slower) | Noticeably faster on lightweight, everyday prompts |
| Quota Savings | Burns Pro quota regardless of task difficulty | Preserves top-tier quota strictly for heavy lifting |
| Consistency | High—you always know exactly which model responded | Variable—depends on how accurately the router judges prompt complexity |
Community Take: Smart Saver or Unnecessary Distraction?
The initial community reaction has been a mix of practical appreciation and lighthearted skepticism.
On one hand, heavy daily users appreciate the quota protection. If you are using Google’s ecosystem of AI assistants and agentic tools for casual brainstorming alongside technical work, burning heavy tokens on a five-word summary feels wasteful.
On the other hand, many power users are asking the obvious question: Is an auto-router what people actually want right now, or would everyone prefer direct access to next-gen frontier models?
“It’s definitely a practical idea for managing compute overhead,” noted one user on social media. “Though picking between a lighter model and a heavier one automatically feels like a pitstop while we all wait for the next major model drop.”
Despite the banter, smart load balancing is quickly becoming an industry standard as platforms work to manage server loads while keeping chat interfaces snappy for everyday power users.
Should You Turn It On?
Here is how to decide whether to flip the switch:
Turn It ON If:
You routinely run into Gemini usage caps or rate-limit warnings during long work sessions.
Your typical workspace session blends low-effort questions with deep technical prompts.
You value fast, low-latency replies for simple queries over raw compute power on every single turn.
Keep It OFF If:
You rely on Gemini exclusively for advanced coding, multi-step logic, or heavy creative writing where you demand maximum reasoning power 100% of the time.
You don’t want an automated system guessing whether your prompt is “simple” or “complex.”
How to Enable Smart Model Selection
Setting it up only takes a couple of seconds:
Open Gemini on your browser or mobile device.
Click your profile icon and navigate to Settings > Advanced Settings.
Look for the Smart model selection option.
Toggle the switch to ON (you can toggle it back off anytime if you prefer manual control).